← BeePostive/System Internals/System Design/Design Scenarios
Scaling a System from 10× to 100×
A system design interview guide to a repeatable method for growing a system by orders of magnitude — measure, find what breaks first, fix it with the cheapest change that works, and repeat — without rewriting everything at once.
“How would you scale this to 10×? To 100×?” is less a question about any one technique than about whether you have a method. The wrong answer is a shopping list — “add caching, sharding, and a queue” — recited without knowing which bottleneck each one relieves. The right answer is a loop: measure the system, find the single resource that saturates first, apply the least invasive fix that removes it, and repeat, because scaling never fails everywhere at once. It fails at one place — the database’s write capacity, a connection pool, a single hot key — and that place moves each time you grow. This guide lays out the loop and then walks the ladder of fixes in the order you actually reach for them, noting what tends to break first at each order of magnitude.
Contents
1. The Method & Scope
Scaling is an iterative process, not a one-shot design. The method is the answer; the techniques are just its steps.
- Measure. Instrument first. You cannot scale what you cannot see — find the resource that saturates (CPU, memory, disk I/O, network, database, locks) using latency percentiles and utilization, not guesses.
- Find the bottleneck. At any load exactly one thing is the limit. Everything else has headroom. Fixing anything but the bottleneck buys nothing.
- Apply the cheapest fix that works. Prefer the least invasive change — a bigger box, a cache, a read replica — over the most invasive — sharding, a rewrite. YAGNI: do not shard for a load you do not have.
- Repeat. The fix moves the bottleneck somewhere else. Re-measure and go again.
Scope. The goal is to grow throughput by 10× then 100× while holding latency and error rate within SLO and keeping cost sane. Correctness and the multi-region story are assumed handled elsewhere; here it is about capacity.
2. Back-of-the-Envelope
Numbers tell you which order of magnitude breaks which resource, so you can predict the next bottleneck instead of discovering it in production.
| Scale | Load (example) | What tends to break first |
|---|---|---|
| 1× | ~1K req/s, one app box + one DB | Fits on a single machine; nothing yet. |
| 10× | ~10K req/s | App CPU and DB connections; single box runs out. |
| 100× | ~100K req/s | DB write throughput and hot rows; one primary can’t keep up. |
| Read/write mix | often 90% reads / 10% writes | Reads → caches + replicas; writes → sharding. |
| Cache hit rate | 90% hits | Cuts DB read load ~10× — the biggest single lever. |
| Connection ceiling | DB caps ~a few hundred connections | Thousands of app threads → pool exhaustion. |
The pattern is consistent: reads scale out cheaply with caching and replicas, but writes are the wall. Somewhere around 100× a single write primary cannot keep up, and that is when the expensive fix — sharding — finally earns its cost.
3. The Scaling Ladder
The fixes come in a natural order, cheapest and least invasive first. You climb only as far as the load forces you — most systems never reach the top rungs.
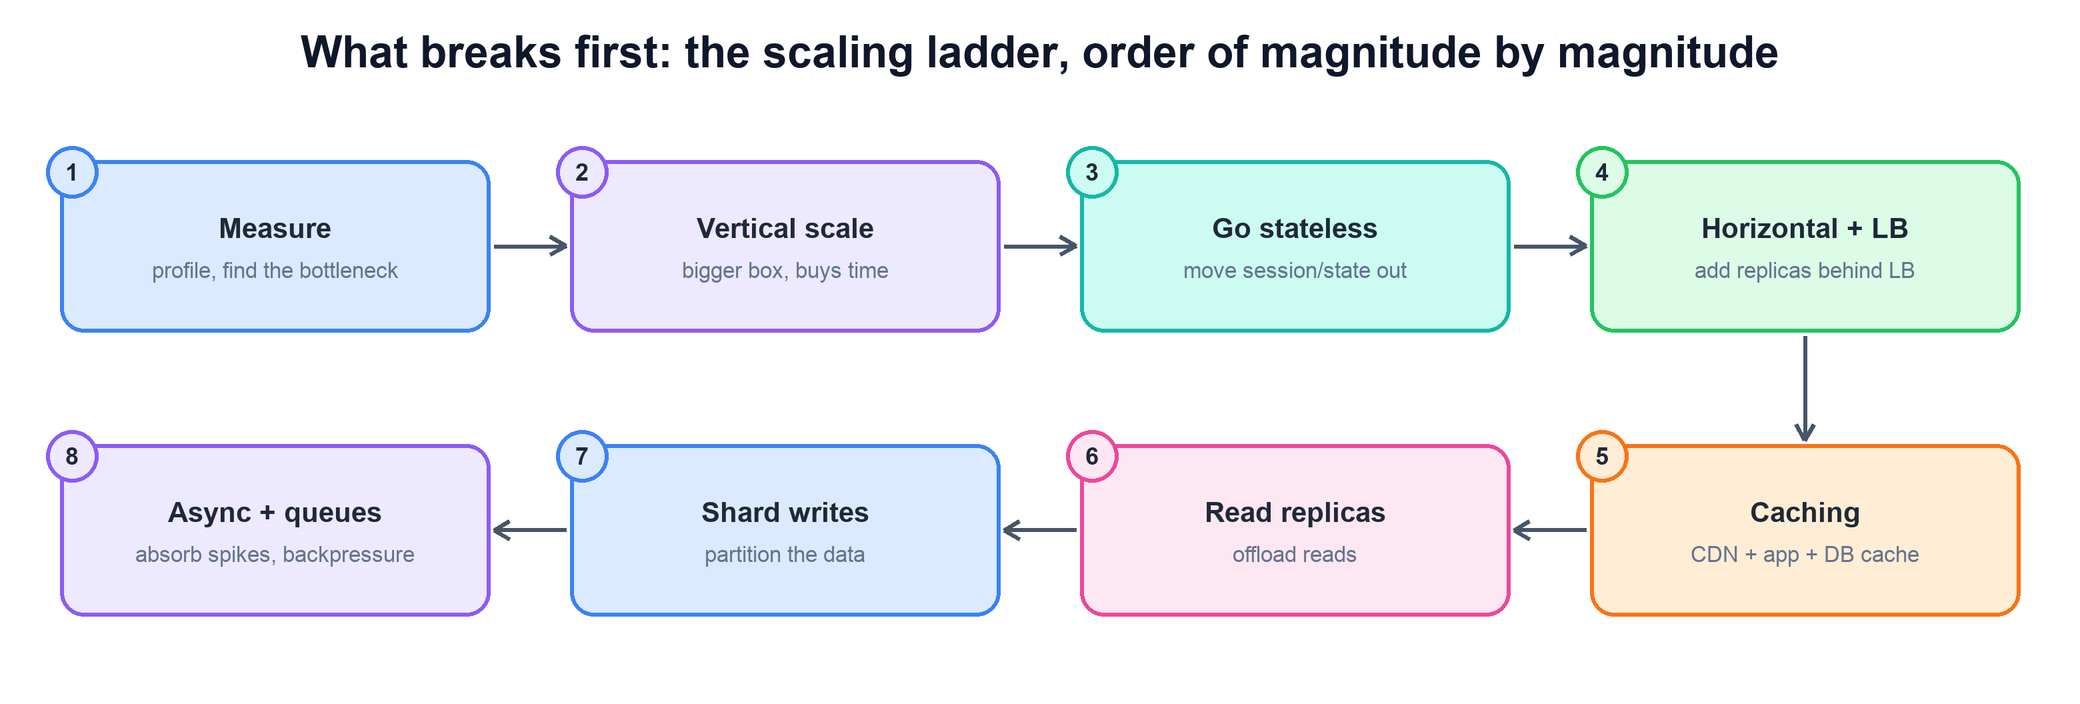
- Vertical scaling — a bigger box — is the first and simplest move. It buys time with zero architectural change, but hits a ceiling (the biggest machine) and a price cliff, so it is a bridge, not a destination.
- Statelessness is the pivot that unlocks everything after it. Once the app holds no per-user state locally — sessions in a shared cache, files in object storage — any instance can serve any request, so you can add and remove instances freely.
- Horizontal scaling puts many stateless instances behind a load balancer. This is where growth becomes elastic: add boxes to add capacity.
Everything below the app tier — caching, replicas, sharding, async — addresses the data layer, which is where scaling gets genuinely hard, and which the rest of this guide covers.
4. A Scaled Architecture
Assembled, the rungs form a familiar layered architecture. Each layer absorbs load so the layer below it sees less.
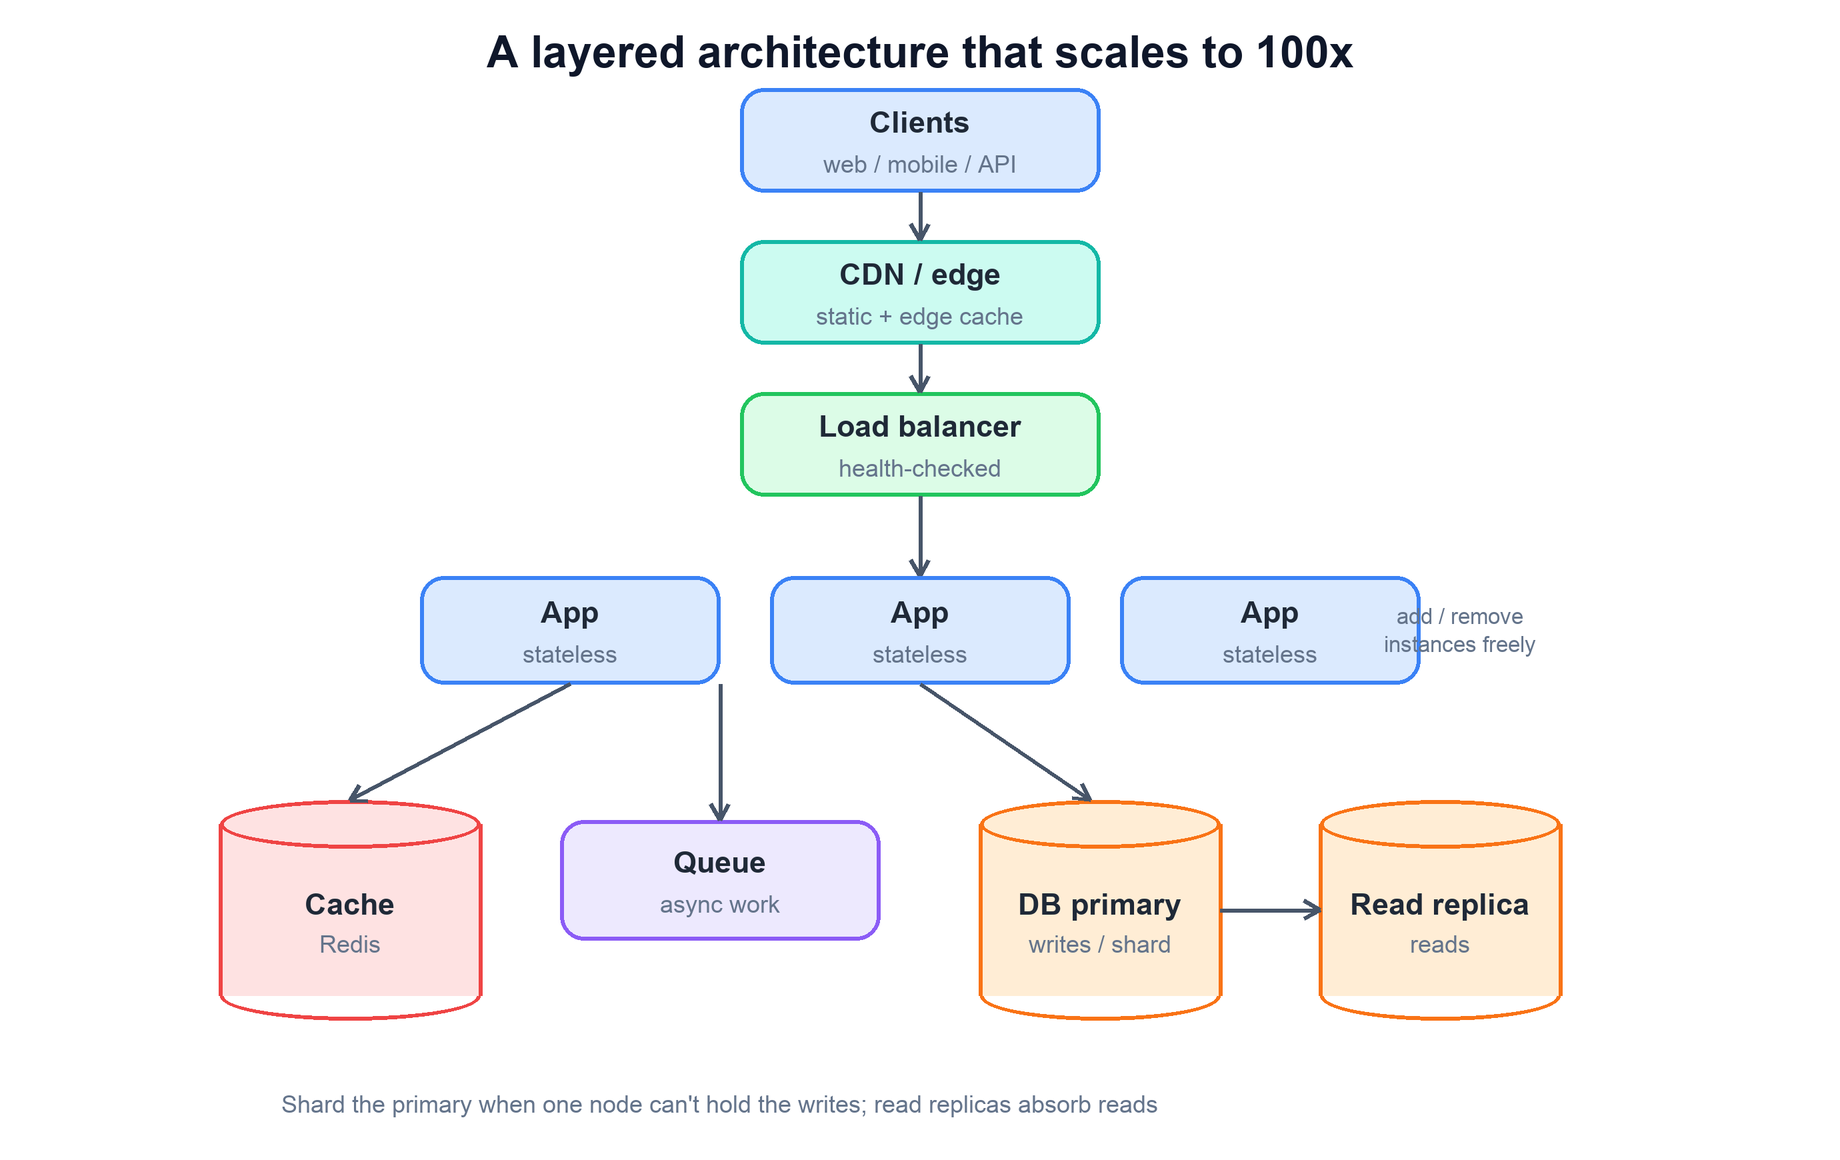
- CDN / edge. Serves static assets and cacheable responses from points of presence near the user, taking the largest slice of traffic off your origin entirely.
- Load balancer. Spreads dynamic traffic across app instances and routes around unhealthy ones.
- Stateless app tier. Scales horizontally; because it holds no local state, autoscaling can add or drop instances with the load.
- Cache. A distributed cache (Redis/memcached) absorbs repeated reads before they reach the database.
- Queue. Moves slow or bursty work off the request path so a spike is absorbed, not dropped.
- Database. A write primary with read replicas for read scale, and sharding once the write volume exceeds a single node.
5. Caching Layers
Caching is the highest-leverage move because it removes work rather than adding capacity. It exists at every layer, and the discipline is to serve each request from the cheapest cache that can answer it.
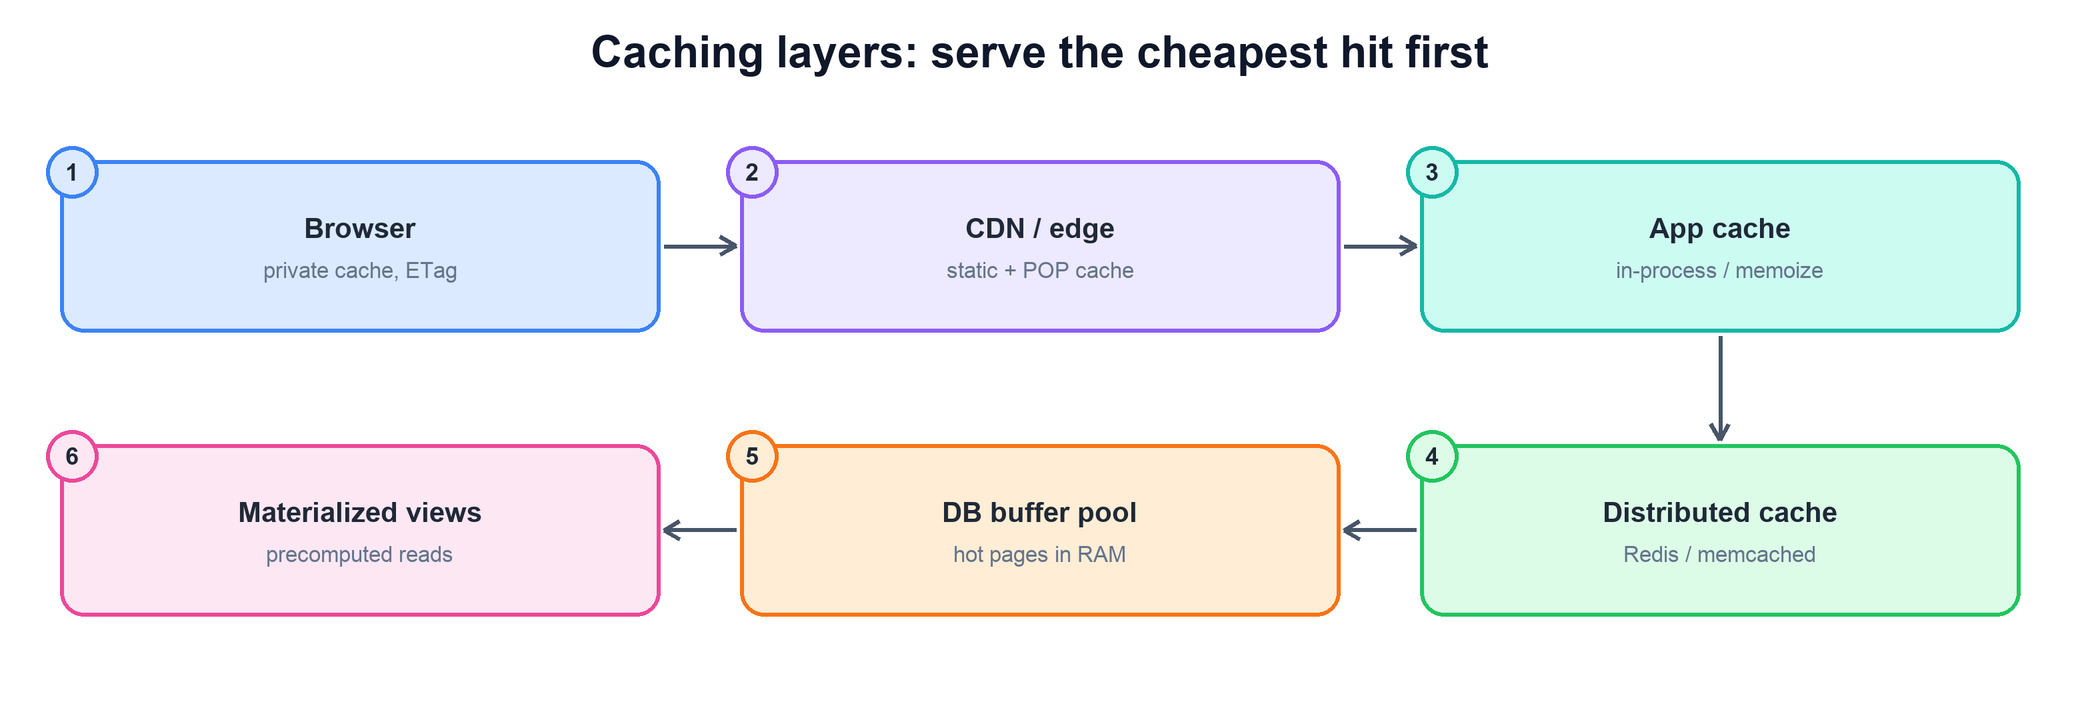
A 90% hit rate cuts backend read load roughly tenfold — often the single biggest lever available. But caching adds its own hard problems, and naming them signals maturity:
- Invalidation. Stale data is the cost of caching; you need a TTL or explicit invalidation strategy, and to decide how much staleness each read tolerates.
- Stampede / thundering herd. When a hot key expires, thousands of requests miss at once and hammer the origin. Mitigate with request coalescing (one fetch fills the cache while others wait), early/jittered expiry, or serving stale while revalidating.
- Hot keys. A single wildly popular key can overload one cache node; replicate or locally cache it.
function read(key):
  v = cache.get(key)
  if v is not None:
    return v                          # fast path: the common case
  with single_flight(key):            # coalesce concurrent misses
    v = cache.get(key)                # re-check after acquiring
    if v is None:
      v = db.read(key)                # only one caller hits the DB
      cache.set(key, v, ttl=jitter()) # jitter avoids synchronized expiry
  return v
6. Replicas, Sharding & Async
When caching is not enough, you scale the data layer itself — reads first, then writes, then everything that does not need to be synchronous.
- Read replicas. Copies of the database that serve reads, letting the primary focus on writes. They scale reads nearly linearly, but replication lag means a replica can serve slightly stale data — route reads that must be current to the primary (read-your-writes).
- Sharding (partitioning). Splitting the data across independent nodes by a shard key so each holds a fraction of the writes. This is the only way past a single primary’s write ceiling, and it is the most invasive change on the ladder — cross-shard queries and transactions get hard, and a bad shard key creates hot shards. Choose a key with high cardinality and even access; consider consistent hashing so adding shards moves minimal data.
- Async & queues. Anything that need not finish before the response — sending email, generating thumbnails, updating search indexes — goes on a queue and is processed by workers. This smooths spikes (the queue absorbs the burst) and shortens the critical path, at the cost of eventual consistency for that work.
7. Connection Limits & Backpressure
Two failure modes bite specifically as you scale out, and both surprise people because they are not about raw compute.
Connection limits. Databases cap concurrent connections at a few hundred, but a horizontally scaled app tier can have thousands of threads each wanting one. Without a bound, the app exhausts the database’s connections and everything stalls. The fix is a connection pool — often a dedicated pooler — that multiplexes many app threads onto a small, bounded set of database connections. The pool size, not the thread count, is the real concurrency limit against the database.
Backpressure. When a downstream component saturates, an unbounded system keeps accepting work it cannot do, queues grow without limit, latency explodes, and it collapses — often taking callers with it in a cascading failure. A well-behaved system pushes back: bounded queues that reject when full, timeouts so callers do not wait forever, load shedding that drops low-priority work early, and circuit breakers that stop hammering a failing dependency. Failing fast under overload is healthier than failing slowly for everyone.
function handle(req):
  if inflight >= max_inflight:
    return 503                         # shed load early, don't queue forever
  with pool.acquire(timeout=50ms) as conn: # bounded DB concurrency
    return conn.query(req, timeout=200ms)  # deadline, don't wait forever
8. Bottlenecks & Tradeoffs
Scaling is a sequence of trades, and the discipline is to make the cheapest one that removes the current bottleneck — no more.
- Vertical vs horizontal. Vertical is simple but ceilinged and priced steeply; horizontal is elastic but demands statelessness and a load balancer. Climb vertically to buy time, then go horizontal.
- Consistency vs performance. Caches and read replicas trade freshness for throughput. Decide per read how much staleness is acceptable; send the few that must be current to the primary.
- Simplicity vs scale. Sharding and async unlock scale but add operational and cognitive cost forever. Defer them until the load is real (YAGNI); premature sharding is a common self-inflicted wound.
- Cost awareness. Every rung costs money — more boxes, more replicas, cross-node traffic. Scaling is an economics problem: the goal is the SLO at the lowest total cost, and sometimes the right answer is to make the workload cheaper (a better query, less data) rather than to buy more capacity.
- Availability under load. The system must degrade gracefully, not collapse. Backpressure, load shedding, and circuit breakers are what turn an overload into slow-but-alive instead of a cascading outage.
9. Summary
Scaling from 10× to 100× is a method, not a menu: measure, find the one thing that breaks first, apply the cheapest fix, and repeat. Reads scale out easily; writes are the wall you climb last.
| Concern | Mechanism |
|---|---|
| Where do we start? | Measure and find the single saturating resource — never optimize blind. |
| What is the first fix? | Vertical scaling to buy time, then statelessness to unlock horizontal scaling. |
| How do we scale reads? | Caching at every layer (biggest lever) plus read replicas for the rest. |
| How do we scale writes? | Shard by a high-cardinality, evenly-accessed key — the expensive fix, used last. |
| How do we handle slow work? | Push it to async queues; absorb spikes and shorten the request path. |
| Why does scaling out stall? | DB connection limits — bound them with a connection pool, not more threads. |
| How do we survive overload? | Backpressure: bounded queues, timeouts, load shedding, circuit breakers — fail fast. |
| How do we stay affordable? | Treat scaling as economics — hit the SLO at the lowest cost, sometimes by shrinking the work. |